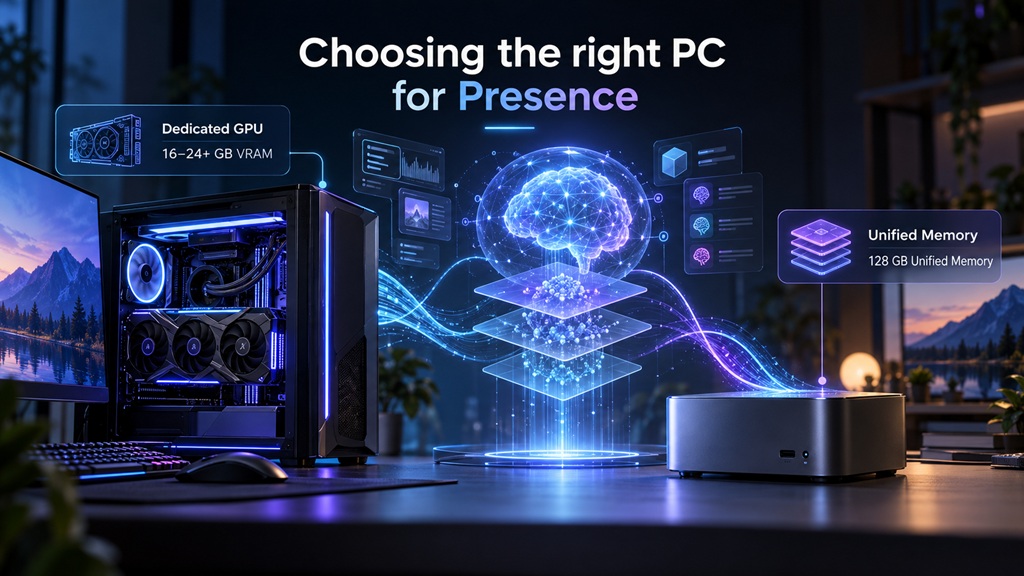
Dedicated graphics cards or unified memory? As local artificial intelligence becomes increasingly accessible, choosing the right computer requires a different approach to hardware specifications.
For decades, choosing a powerful computer was relatively straightforward. A faster processor, a better graphics card, and more RAM generally meant better performance. Gamers focused on frame rates, professionals on processing power, and most other users simply bought the fastest machine their budget allowed.
Local artificial intelligence is changing those priorities.
With increasingly capable AI models running directly on personal computers, without relying on cloud servers, memory capacity has become one of the most important factors in hardware selection. And the traditional assumption that a powerful dedicated graphics card is always the best solution no longer tells the whole story.
Two distinct approaches are emerging: conventional desktop PCs equipped with dedicated GPUs, and compact systems offering large amounts of unified memory.
Both have advantages. But they serve somewhat different purposes.
- Why memory matters so much for local AI
- The traditional approach: a desktop with a dedicated GPU
- AMD Strix Halo: a different approach to AI computing
- Running models with more than 100 billion parameters
- Capacity versus speed: understanding the trade-off
- What about Apple Silicon?
- Local AI software is becoming more accessible
- Can a computer use multiple GPUs for AI?
- How much RAM and storage should you buy?
- Which type of PC should you buy for local AI?
- The future of personal AI may depend more on memory than raw power
Why memory matters so much for local AI
Large language models contain billions of parameters, essentially the numerical values learned during training that determine how the models process and generate information.
Those parameters must be stored somewhere while the model is running.
For most GPU-accelerated inference systems, the ideal situation is to keep the entire model, along with the additional memory required for execution, within memory directly accessible to the graphics processor.
This is where conventional computers can encounter a bottleneck.
An NVIDIA GeForce RTX 5080, for example, offers 16 GB of dedicated graphics memory, while the RTX 4090 provides 24 GB and the RTX 5090 offers 32 GB.
These are extremely powerful GPUs, capable of impressive performance in gaming, image generation, video processing and many AI workloads.
However, their computational power does not eliminate their memory limitations.
A model requiring 50 or 60 GB cannot fit entirely within a 16 GB graphics card. Some inference frameworks can compensate by offloading portions of the model into conventional system RAM, but transferring data between system memory and the GPU introduces substantial performance penalties.
In other words, a faster graphics processor cannot accelerate a model that does not fit into its available memory without making compromises elsewhere.
Memory bandwidth, computational performance and software optimization still matter enormously. But memory capacity often determines which models can be used efficiently in the first place.
The traditional approach: a desktop with a dedicated GPU
For most users who want a computer capable of both gaming and AI, a desktop with a dedicated graphics card remains an excellent choice.
Modern GPUs offer exceptional memory bandwidth and specialized hardware for accelerating neural-network computations.
NVIDIA also benefits from a mature software ecosystem, with broad support across machine-learning frameworks and generative AI applications.
For users primarily interested in creating images, generating videos or running models where inference speed matters more than model size, a high-end dedicated GPU often provides the strongest experience.
AMD’s dedicated graphics cards are also relevant, particularly models offering generous VRAM capacity, although compatibility and optimization may vary between inference frameworks.
The main disadvantages are cost, power consumption and, above all, the limited memory capacity available on individual consumer GPUs.
Even powerful graphics cards can struggle with models that exceed their VRAM capacity.
For anyone building a new AI-capable desktop, 16 GB of VRAM is a reasonable starting point. Moving to 24 GB or 32 GB considerably expands the range of models that can run without substantial offloading.
But there is another approach worth considering.
AMD Strix Halo: a different approach to AI computing
AMD’s Ryzen AI Max family, commonly known by its development codename Strix Halo, offers an interesting alternative to the traditional desktop architecture.
The flagship Ryzen AI Max+ 395 combines 16 Zen 5 CPU cores with an integrated Radeon 8060S GPU featuring 40 RDNA 3.5 compute units.
Its most interesting feature for local AI, however, is not simply processing power.
It is memory architecture.
Unlike a conventional desktop GPU with a fixed amount of dedicated VRAM, Strix Halo uses unified memory shared between the CPU and integrated GPU.
Systems equipped with 128 GB of RAM can make up to 96 GB available to the graphics processor through AMD’s Variable Graphics Memory technology, depending on the system configuration.
This does not make Strix Halo equivalent to a high-end dedicated GPU with 96 GB of specialized graphics memory. Its bandwidth and computational performance are considerably different.
What it does provide is something unusual in a compact consumer computer: enough GPU-accessible memory to accommodate AI models that would otherwise require substantially more expensive hardware configurations.
And that changes the economics of experimenting with large language models.
Running models with more than 100 billion parameters
Consider OpenAI’s GPT-OSS 120B, an open-weight model containing approximately 117 billion parameters.
Thanks to its mixture-of-experts architecture and quantization, the model’s published checkpoint occupies approximately 61 GiB, while practical execution also requires memory for additional runtime components and context.
OpenAI has demonstrated deployments on single GPUs with 80 GB of memory, and supported inference implementations can operate with lower memory requirements.
For a conventional consumer GPU with 16 GB or 24 GB of VRAM, running a model of this size entirely on the graphics card is not possible.
A Strix Halo system with 128 GB of unified memory offers enough capacity to make such experiments feasible, provided the inference backend supports the model and hardware configuration.
That does not mean inference will be exceptionally fast.
Large models remain computationally demanding, and Strix Halo’s integrated GPU cannot match the throughput of specialized high-end accelerators.
But there is a fundamental distinction between running a model more slowly and being unable to load it in the first place.
For researchers, enthusiasts and users interested in experimenting with large models locally, that distinction can be decisive.
Capacity versus speed: understanding the trade-off
It would be misleading to describe Strix Halo as universally superior to a powerful NVIDIA or AMD desktop GPU.
The two architectures solve different problems.
A dedicated GPU usually offers substantially greater bandwidth and computational throughput, making it especially attractive for latency-sensitive applications, image generation and demanding video workloads.
Strix Halo prioritizes another characteristic: the amount of memory that can be made available to its integrated graphics processor.
This makes it particularly interesting for workloads involving large language models, where memory capacity can be a more restrictive constraint than raw processing performance.
Gaming introduces another consideration.
Although the Radeon 8060S is a capable integrated GPU, users who prioritize demanding games at high resolutions will generally obtain better results from a desktop equipped with a powerful dedicated graphics card.
Likewise, Strix Halo computers are not necessarily cheaper than traditional desktops. Prices vary considerably, and buyers should compare complete configurations rather than individual components.
Their appeal lies in the combination of high unified-memory capacity, compact dimensions and relatively modest power requirements.
What about Apple Silicon?
AMD is not alone in exploring the advantages of unified memory.
Apple Silicon has used a unified-memory architecture for years, allowing CPU and GPU components to access a shared memory pool.
This design has helped make Macs increasingly attractive for running local AI models, particularly through software optimized for Apple’s Metal framework.
As with Strix Halo, available memory capacity is an important consideration.
A Mac with 16 GB of unified memory can run smaller quantized models, while configurations with 24 GB, 32 GB, 64 GB or more provide increasing flexibility.
The performance of individual Apple chips also varies considerably, so memory capacity should never be treated as the only relevant specification.
Nevertheless, both Apple’s approach and AMD’s Strix Halo architecture highlight a growing trend: high-capacity unified memory is becoming an important alternative to dedicated graphics memory for local AI workloads.
Local AI software is becoming more accessible
Hardware is only part of the story.
Running local AI models has traditionally involved selecting compatible model formats, configuring inference engines, managing GPU resources and dealing with hardware-specific limitations.
These requirements can be manageable for experienced developers but intimidating for ordinary computer users.
A new generation of consumer-oriented applications is attempting to remove that complexity.
One example is Blacknode Presence, a locally running AI assistant designed to automatically adapt its model configuration to the hardware available.
Rather than requiring users to manually select and configure every model, Presence detects system resources and uses different performance tiers to determine which models can run efficiently.
Configurations with approximately 16 GB of dedicated VRAM can support its middle tier, while more capable GPUs and high-memory systems such as Strix Halo can accommodate its larger models.
An interesting aspect of Presence’s architecture is its ability to run multiple AI models with different responsibilities.
For example, a larger conversational model can handle the primary interaction while a smaller model performs supporting tasks.
The software also supports dual-GPU configurations, automatically assigning separate models to different graphics cards during installation.
This should not be confused with combining the memory of two GPUs for a single model. Two graphics cards with 16 GB each remain separate memory devices, even when different AI models are distributed between them.
Blacknode’s development team has tested Presence on both dedicated-GPU desktops and a 128 GB Strix Halo machine, using these different systems to evaluate hardware profiles and model behavior.
The broader significance is straightforward: consumer AI software increasingly needs to adapt to the computer, rather than requiring the user to adapt the computer to the software.
Can a computer use multiple GPUs for AI?
Multi-GPU systems deserve special attention because they can be misunderstood.
There are two fundamentally different approaches to using multiple graphics cards.
The first assigns different workloads to separate GPUs.
One card might run a conversational model, while another executes a smaller assistant model or performs an independent task.
This approach can improve overall responsiveness and allow applications to run several models simultaneously.
The second approach distributes a single large model across multiple GPUs.
This requires specific support from the inference engine and introduces additional considerations related to communication between devices, memory distribution and processing overhead.
Simply installing two GPUs does not automatically combine their memory.
Two 16 GB graphics cards do not magically become a single 32 GB graphics processor.
For consumers, this distinction matters because buying additional hardware without understanding the software’s capabilities can quickly become an expensive mistake.
How much RAM and storage should you buy?
The right answer depends heavily on how the computer will be used.
For a conventional desktop with a dedicated GPU, system RAM remains important for the operating system, applications and any AI workloads that cannot fit entirely in VRAM.
However, increasing system RAM does not directly increase the dedicated memory available to the graphics processor.
On unified-memory systems, the relationship is different because CPU and GPU draw from the same pool.
A 64 GB Strix Halo configuration can be useful for many local AI tasks, but buyers specifically interested in exceptionally large language models should seriously consider the 128 GB version.
Storage is another commonly overlooked requirement.
Individual language models can occupy several gigabytes or tens of gigabytes, and users experimenting with multiple models will quickly accumulate substantial downloads.
A fast NVMe SSD is therefore highly recommended, with 2 TB providing a comfortable starting point for a new machine intended for regular AI experimentation.
Finally, software compatibility remains essential.
GPU drivers, supported inference backends, model quantization formats and operating-system support can all determine whether a particular combination works efficiently.
Enough memory is necessary, but it is not a guarantee of compatibility.
Which type of PC should you buy for local AI?
There is no universally correct answer.
For gamers, content creators and users interested in fast image or video generation, a desktop with a capable dedicated GPU remains the most versatile option.
For users primarily interested in running very large language models locally, a 128 GB Strix Halo computer offers a compelling alternative, particularly when space, power consumption and memory capacity are important considerations.
Apple Silicon provides a third option, especially for those already working within the macOS ecosystem.
And for users who simply want a practical local AI assistant, existing computers may already be sufficient, depending on the software and models involved.
The most important advice is to avoid buying hardware based solely on processor benchmarks or marketing claims about AI performance.
Instead, consider three questions:
- How much memory does the AI model need?
- How quickly do I need it to run?
- Does the software I intend to use support my chosen hardware?
Those questions are more useful than a headline advertising billions of operations per second.
The future of personal AI may depend more on memory than raw power
As AI models become more capable, hardware manufacturers face competing demands.
Users want faster inference, larger models, lower power consumption and affordable prices. Achieving all four simultaneously is difficult.
Dedicated GPUs will continue to offer major advantages, particularly where performance and software maturity are essential.
But high-capacity unified-memory systems are opening another path, making it possible to experiment with substantial AI models on compact computers that would previously have been considered unsuitable for such workloads.
At the same time, quantization, better inference engines and increasingly efficient model architectures continue to reduce hardware requirements.
This means today’s limitations may not be tomorrow’s.
For consumers planning their next computer purchase, the lesson is not that dedicated GPUs have become obsolete, nor that unified memory is the solution to every problem.
It is that local AI has changed what makes a computer powerful.
And understanding that difference may be the best way to avoid spending a great deal of money on the wrong machine.